Legal AI Models, Retrieval, and Agents
From Chinese legal foundation models and user-centric evaluation to generative retrieval, agentic reasoning, and continuously improving legal AI systems.
The team has built a systematic Legal AI foundation spanning domain-model training, real-user evaluation, legal knowledge retrieval, and agentic evidence-based reasoning. The research has evolved from training a Chinese legal model to connecting models, legal databases, tools, benchmarks, and lawyer workflows in a continuously improving closed loop.
Research Evolution
A 7B Chinese legal model trained on approximately 60 GB of cases, statutes, complaints, and legal news, supporting legal question answering, dialogue, and document generation.
Moves from knowledge-centric legal exams to user-centric evaluation with five legal scenarios and 22 tasks grounded in surveys and validation by legal professionals.
Reframes legal retrieval as direct prediction of relevant article identifiers, connecting a legal question to structured statutory memory instead of relying only on embedding similarity.
Extends one-shot RAG into a Think → Retrieve → Rethink → Retrieve → Answer process that actively identifies missing evidence and revises reasoning.
Connect real lawyer use, expert edits, data accumulation, benchmark updates, and model training into a sustainable improvement cycle.
Four Research Foundations
Early full-parameter Chinese legal LLM work covering corpus construction, continual pre-training, instruction tuning, and deployment.
RepositoryFindings of NAACL 2025, pp. 7960–8003. It asks whether a model can complete the work legal professionals actually need.
PaperCombines legal agents, databases, iterative retrieval, and traceable evidence in a multi-step reasoning process.
OpenReviewUses the structure of statutory knowledge to retrieve law through article identifiers rather than only vector matching.
OpenReviewHarness → Benchmark → Training → Loop
Connect legal databases, case repositories, contracts, knowledge graphs, retrieval interfaces, and reusable Legal Skills so agents can act in real workflows.
Derive tasks from lawyer practice and involve legal professionals in rubric design, expert evaluation, and authoritative validation.
Use expert edits and evaluation data for supervised fine-tuning, rubric-based reinforcement learning, and legal retrieval training.
Turn adoption, modification, scoring, and business outcomes into new training data and benchmark updates.
Model building → evaluation → workflow automation → real-user pilots → data feedback and iteration. This is the core Loop Engineering path for reliable, explainable, and trustworthy Legal AI.
Joint Laboratory and Real-World Agenda
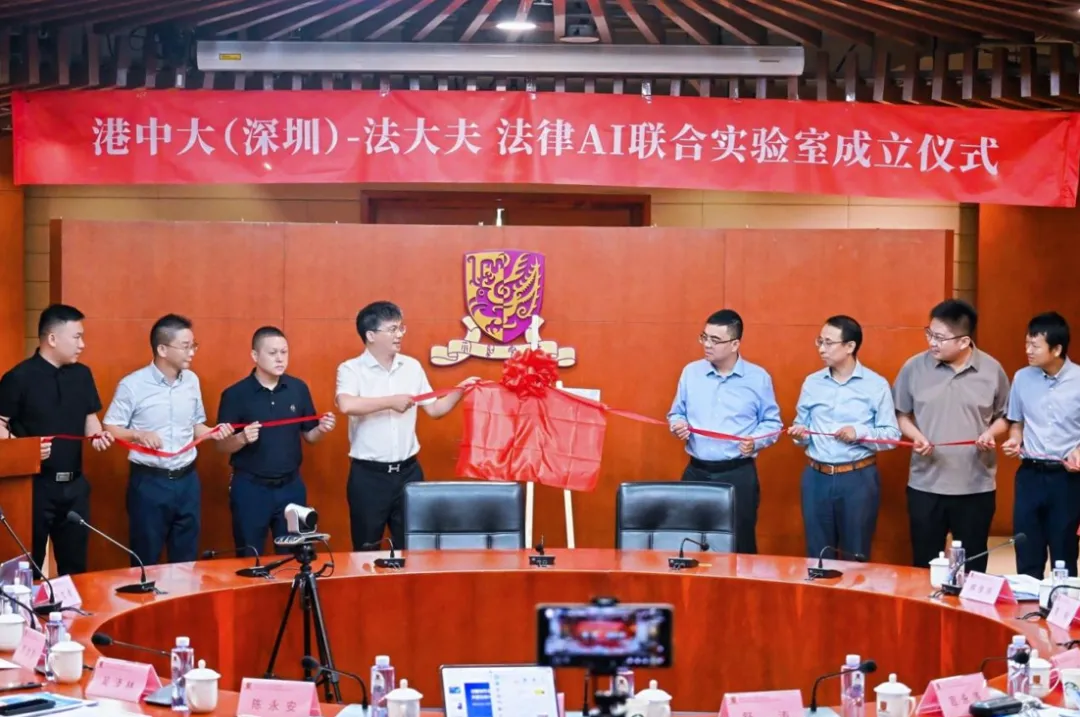
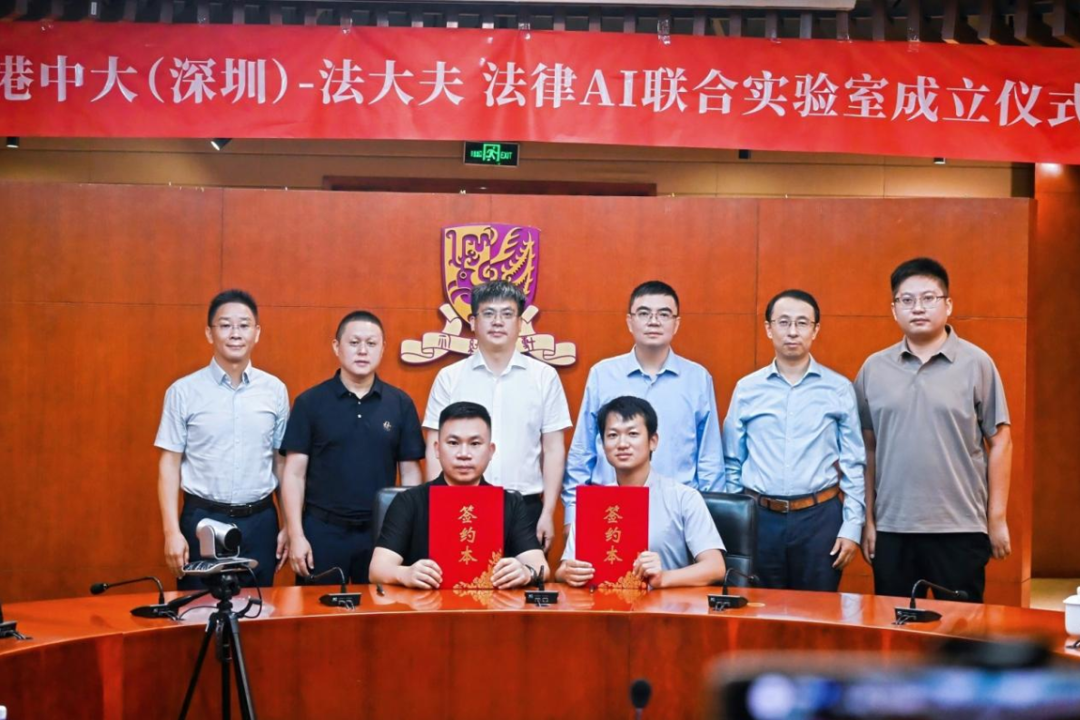
- Core research: legal reasoning, hallucination reduction, factual evidence chains, privacy, and security.
- Priority scenarios: intelligent contract review, enterprise compliance and risk control, and public legal services.
- Operating model: university-led frontier research plus enterprise-led scenario validation and productization.
Why It Matters
The next step is not another isolated legal LLM. It is a Legal AI system in which models, structured legal knowledge, tools, benchmarks, expert feedback, and real lawyer workflows improve together.